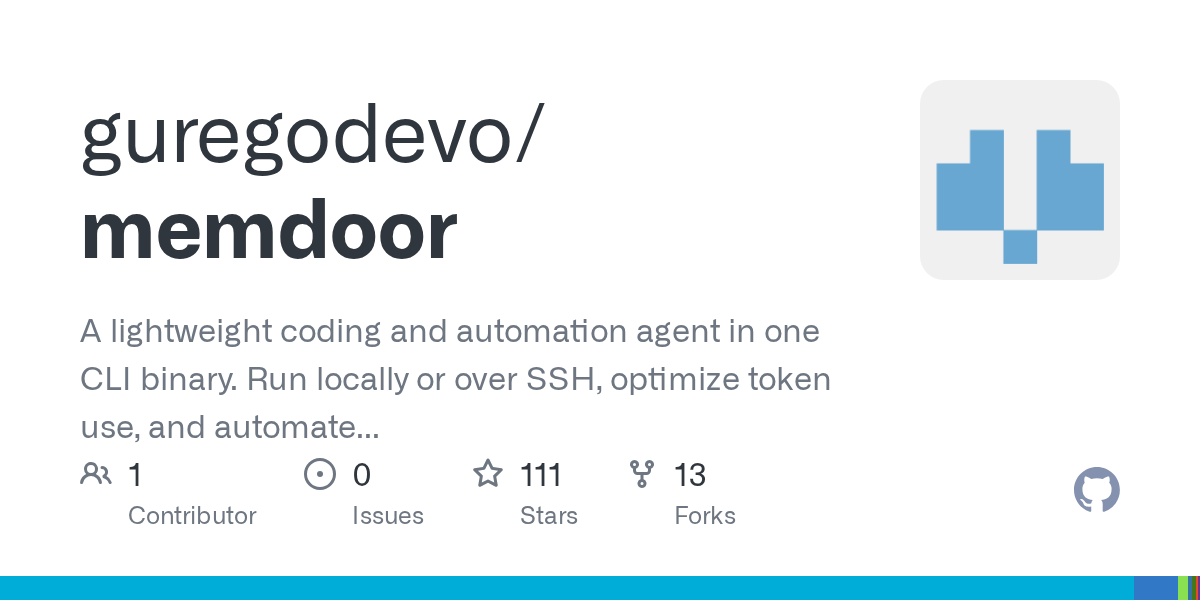
A new entry on GitHub claims that a team of five Qwen3.8-27B models beats Fable 5 on LiveCodeBench Hard, a demanding benchmark for AI coding. The result appears in the Memdoor repository from developer guregodevo, which describes itself as a lightweight coding and automation agent built into a single CLI binary.
The significance is straightforward: LiveCodeBench Hard is designed to test code generation on difficult problems, so a multi-model Qwen3.8-27B setup outperforming Fable 5 suggests that open-weight models can compete at the top of coding benchmarks when combined in a team. The repository does not provide a full technical paper, so the result should be treated as a project claim rather than an independently verified study.
What the Memdoor team-solve result says
According to the Memdoor repository, the team-solve workflow is an example under examples/workflows/team-solve, with folders for bench, sample, and steps. This indicates that the project includes a benchmarking setup specifically for comparing the team approach on coding tasks.
The README for the workflow is not fully reproduced in the source text, so details such as exact scores, model versions, and run conditions are not confirmed here. No specific benchmark score, date, or configuration is given in the available source. Readers should check the repository directly for the precise numbers.
- Claimed result: five Qwen3.8-27B models as a team beat Fable 5 on LiveCodeBench Hard.
- Source: GitHub repository guregodevo/memdoor.
- Workflow path: examples/workflows/team-solve with bench, sample, and steps directories.