Meta has published a detailed look at Prometheus, its gigawatt-scale AI supercluster in New Albany, Ohio. The first phase is already complete, and the company says the site is being scaled toward roughly 1 million GPUs at full capacity, according to a post on Meta's engineering blog dated October 19, 2026.
Prometheus was used to train Meta's Muse family of foundational models, including the Muse Wonder models, which the company describes as its new frontier models for personal and professional agentic tasks. The disclosure matters because Meta is competing with other big tech firms in an AI infrastructure race where compute capacity increasingly decides which models get built first.
Prometheus supercluster specs and scale
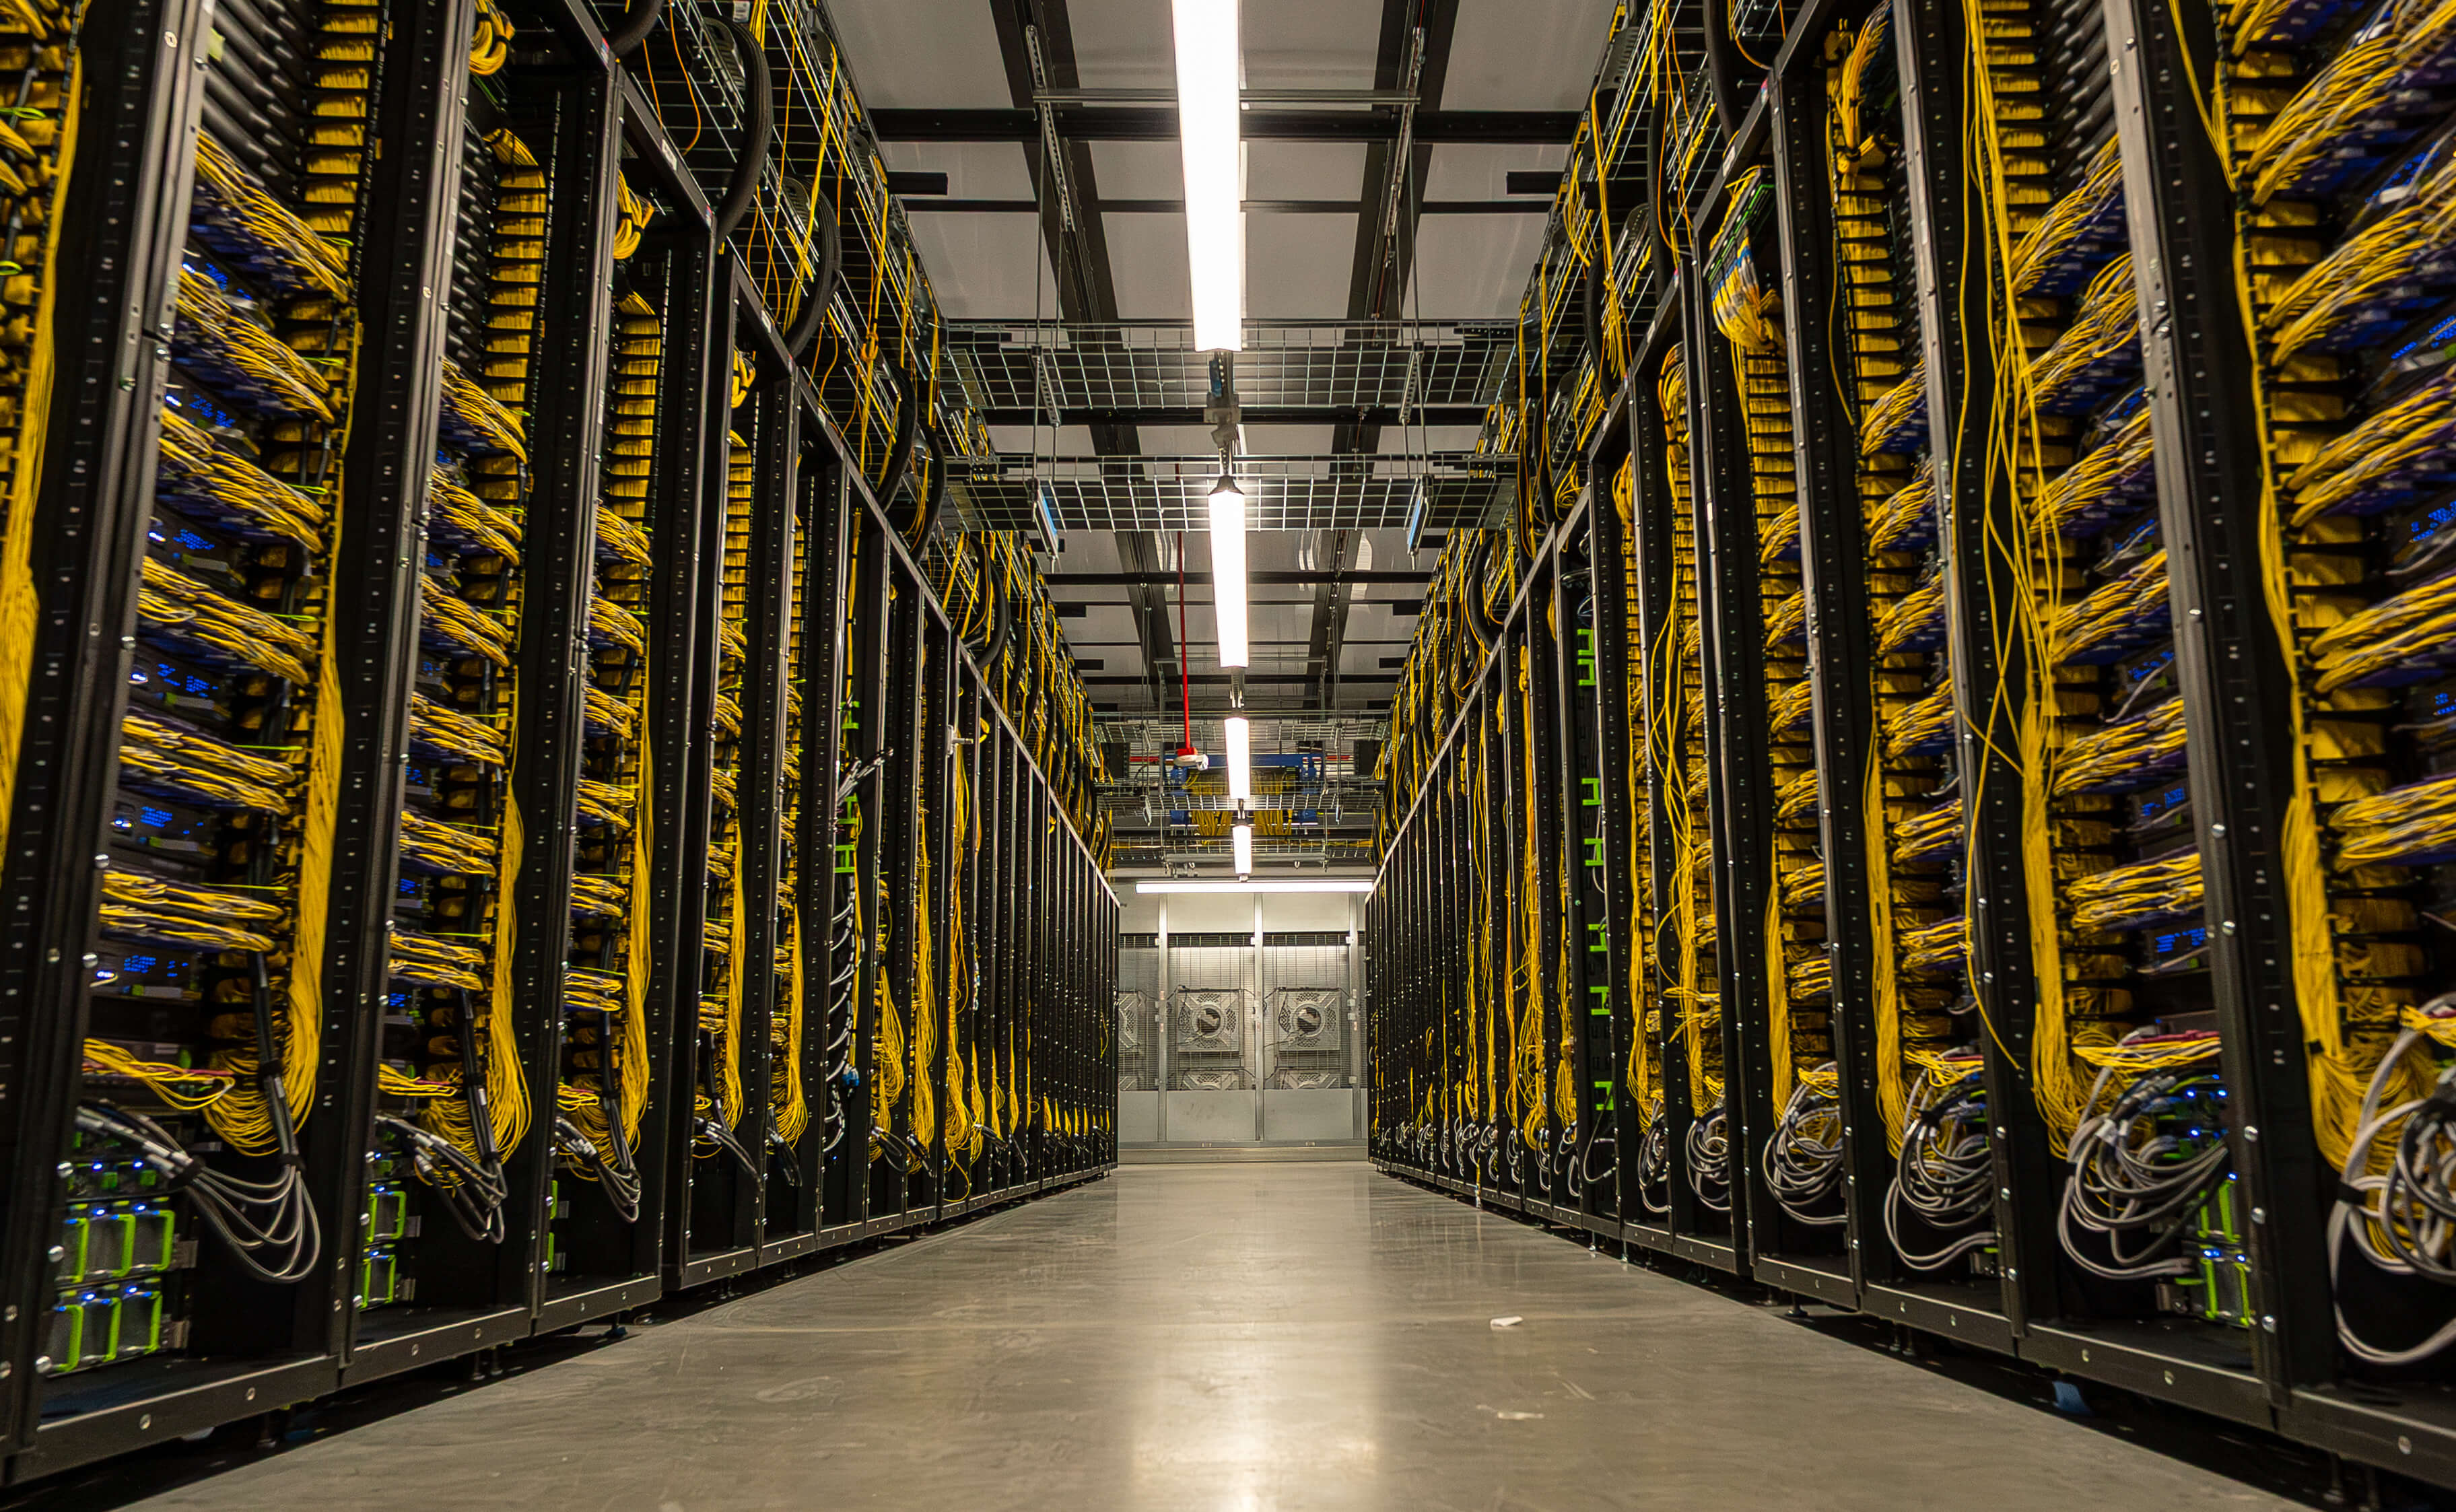
Meta says Prometheus today spans hundreds of thousands of GPUs across multiple interconnected buildings in New Albany, tied together by miles of fiber and operating as a single machine. The site was a conventional data center running web traffic until about two years ago, when Meta redesigned it for frontier model training.
At full scale, the supercluster is expected to hold roughly 1 million distributed GPUs working in lockstep. Meta says the added capacity lets it pursue larger models and longer context windows than were previously practical, and that the buildout continues with Meta Superintelligence Labs' next frontier models in mind.
- Location: Meta's New Albany, Ohio data center
- Full-scale target: roughly 1 million distributed GPUs
- First phase: complete, used to train the Muse foundational models